85% smaller LLMs. Better than llama.cpp's own 2-bit at the same size.
We compress models you already have to 2 bits, with no retraining. Qwen3-4B goes from 8.05 GB to 1.24 GB, and at that size its WikiText-2 perplexity is 16.64 against 28.61 for llama.cpp's IQ2_XXS (lower is better).
Windows and Linux · NVIDIA RTX 30/40/50 · runs on our patched llama.cpp (CUDA)
Real time, not sped up. Text and timing come from a real run of Pingala-8 Qwen3-4B (1.24 GB) on an RTX 5070 Ti Laptop GPU; the chat window is recreated.
Qwen3-4B: 8.05 GB fp16 to 1.24 GB. Llama-3.1-8B: 16.08 GB to 2.39 GB.
vs 28.61 for IQ2_XXS and 18.15 for IQ2_KT at the same size (Qwen3-4B, WikiText-2, lower is better).
50.8 vs 41.9 over five zero-shot tests, keeping 90% of the 8-bit original's 56.3.
Batch 1. Also 39% faster than Q4_K_M at half its size. Reading prompts is slower (0.74x).
Results
Same bytes, better model
Every number on this page comes from the paper and the logs in the code repository. Our shipped file is called B4 in the chart.
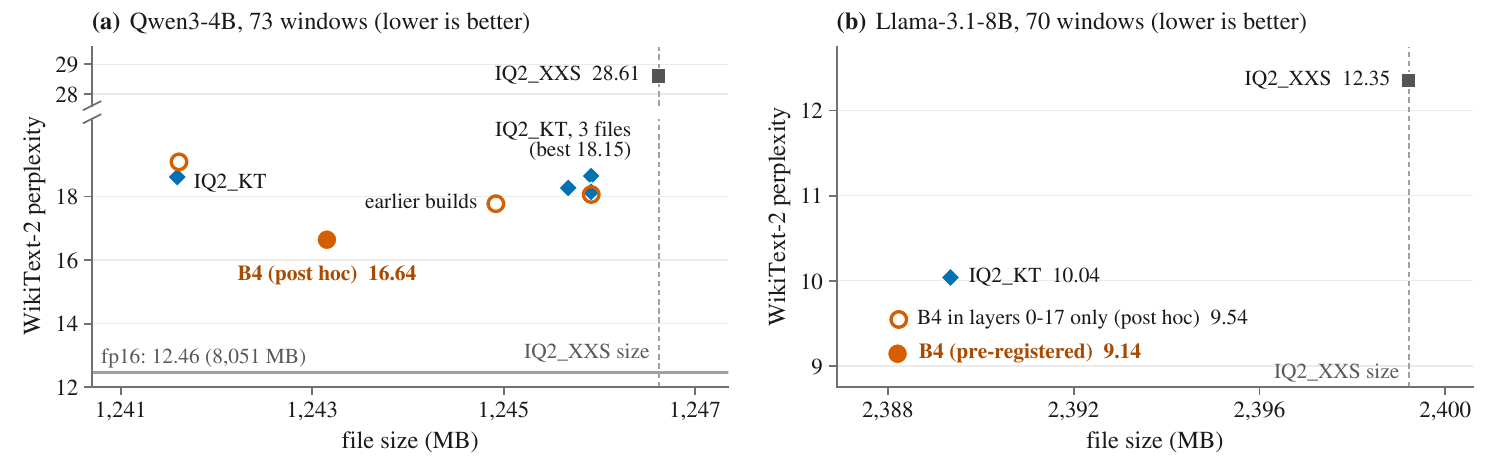
How it compares on Qwen3-4B
| Format | Size | Perplexity | What it is |
|---|---|---|---|
| fp16 original | 8.05 GB | Uncompressed reference | |
| Ternary Bonsai 4B (prism-ml) | 1.07 GB | Retrained model; needs a training run and their fork | |
| GSQ Q2_K (ISTA-DASLab) | 1.67 GB | Compression, 34% bigger file | |
| Pingala-8 B4 ours | 1.24 GB | Compression of the original, no retraining | |
| IQ2_KT (ik_llama.cpp) | 1.25 GB | Compression, same size | |
| IQ2_XXS (llama.cpp) | 1.25 GB | Compression, same size |
WikiText-2 test, context 4096, lower is better. If you just want the strongest small Qwen3-4B, a retrained model like Ternary Bonsai scores higher. Pingala-8 is for compressing models nobody has retrained for you: among the formats we tested, it gives the lowest perplexity for the original Qwen3-4B at this size without retraining.
Zero-shot quiz scores, Qwen3-4B
| Test | 8-bit original | IQ2_XXS | IQ2_KT | Ours | vs IQ2_XXS |
|---|---|---|---|---|---|
| ARC-Easy | 66.1 | 43.9 | 53.3 | 60.9 | +39% |
| ARC-Challenge | 45.2 | 29.1 | 35.1 | 37.8 | +30% |
| HellaSwag | 65.8 | 47.8 | 53.3 | 57.7 | +21% |
| WinoGrande | 65.5 | 57.5 | 57.9 | 63.8 | +11% |
| MMLU | 38.7 | 31.1 | 32.9 | 34.0 | +9% |
| Average | 56.3 | 41.9 | 46.5 | 50.8 | +21% |
All 2-bit files are the same 1.24 GB. Accuracy in %, higher is better.
Llama-3.1-8B, pre-registered
| Format | Size | PPL, BOS | PPL, strided |
|---|---|---|---|
| fp16 original | 16.08 GB | - | - |
| Pingala-8 B4 ours | 2.39 GB | 8.44 | 9.14 |
| IQ2_KT | 2.39 GB | 9.36 | 10.04 |
| IQ2_XXS | 2.40 GB | - | 12.35 |
WikiText-2, lower is better. "BOS": a BOS token at every window. "Strided": the protocol in the chart above. The win over IQ2_KT was predicted in writing before the file was built.
Faster than Q4_K_M at half its size. On one RTX 5070 Ti Laptop GPU, batch-1 generation runs at 1.10x the speed of llama.cpp's IQ2_XXS. Prompt processing is slower (0.74x), so long pasted documents take longer to read in.
Honest limits
Where we lose
Please read these before you pick a format. We would rather you know them up front.
Qwen3-14B: IQ2_KT wins
Perplexity 9.57 for us against 9.40 for IQ2_KT (a tie on C4). We wrote the prediction down before the run, so this is a real loss.
A retrained model scores higher
Ternary Bonsai 4B reaches 11.59 at 1.07 GB. It is a retrained model, not a compression of Qwen3-4B, and needs a training run plus its own fork.
Prompt reading is slower
Prompt processing runs at 0.74x the speed of IQ2_XXS, and serving several chats at once is 3 to 5 times slower.
Patched llama.cpp, CUDA only
Stock llama.cpp, Ollama and LM Studio cannot load these files yet. No Metal or Vulkan path. Speed was measured on one laptop GPU.
The Qwen3-4B file is tuned
It is the last of many builds evaluated on WikiText-2, so treat that result as post hoc. C4 text, Llama-3.1-8B and Qwen3-14B were held out or pre-registered.
2 bits still costs quality
The model is clearly worse than full precision: 16.64 against 12.46 perplexity for fp16 Qwen3-4B.
Try it
Chatting in about two minutes
Windows, NVIDIA RTX 30/40/50 with a recent driver. No Python, no build step.
Unzip and double-click
Run run_qwen3_4b.bat (or run_llama31_8b.bat). The model downloads once from this Hugging Face org.
Chat
A chat page opens at http://127.0.0.1:8080 in your browser. Close the black window to stop.
# Linux, from the same release
./run.sh qwen      # or: ./run.sh llama
# then open http://127.0.0.1:8080

# Build from source and reproduce the numbers
git clone https://github.com/Genrius-AI/pingala8-llm   # see README.md and REPRODUCE.md
Get the files
Models, code and paper
GGUF files for the patched llama.cpp runtime. Pass the first shard; llama.cpp finds the others. Everything is also in one Hugging Face collection.
Qwen3-4B Pingala-8 2-bit
1.24 GBFrom 8.05 GB. Perplexity 16.64 vs 28.61 for IQ2_XXS at the same size. Works with the one-click chat build.
Genrius-AI/Qwen3-4B-Pingala8-2bit →Llama-3.1-8B Pingala-8 2-bit
2.39 GBFrom 16.08 GB. Pre-registered win over IQ2_KT: 8.44 vs 9.36. Base model, best for plain text completion. Built with Llama.
Genrius-AI/Llama-3.1-8B-Pingala8-2bit →Code and patch
CUDA patch for llama.cpp, build scripts and every log behind these numbers.
GitHub →One-click build
Windows zip with the patched runtime and a browser chat page. Linux script included.
Release v2.4 →Paper
Small-State Coset Trellis Coding at IQ2_XXS Size: An Equal-Bytes Study in llama.cpp.
DOI 10.5281/zenodo.23481757 →How it works
A small trellis code, inside a GGUF file
Pingala-8 stores an 8-state trellis code (Ungerboeck's set partitioning) over groups of 4 weights. Before coding, each weight matrix goes through a random Hadamard rotation and QuIP-style LDLQ rounding, and input-column scales are set by minimising an incoherence bound.
The result is a normal GGUF file at no more bytes than llama.cpp's IQ2_XXS, decoded on the GPU by a CUDA patch to llama.cpp. It builds on QTIP and QuIP# and on ikawrakow's IQ2_KT.
Compressing a model takes a few hours on one GPU. There is no retraining: the rounding step only needs some calibration text.
Cite
If you use Pingala-8
@misc{goyal2026pingala8,
  title     = {Small-State Coset Trellis Coding at IQ2_XXS Size:
               An Equal-Bytes Study in llama.cpp},
  author    = {Goyal, Harshit},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.23481757},
  url       = {https://doi.org/10.5281/zenodo.23481757}
}